Staff platform engineer, Bristol
I make cloud platforms faster, cheaper and quieter at 3 a.m.
Ten years after graduating in computer science I work as a staff engineer on the platform that 200 engineers deploy to. I like measurable work: a latency, a bill, an uptime figure, a page that did not go off.
Where I focus
Reliability
Service level objectives, on-call that people can sustain, and incident reviews that change the system rather than blame a person.
Performance and cost
Profiling first, then fixing the one thing that matters. I report savings in pounds and milliseconds, not in effort.
Platform and developer tools
Deploy pipelines, service templates and internal docs that make the safe way the easy way for teams I do not manage.
Technical direction
Writing design documents, reviewing other teams' designs and deciding with them what not to build.
Selected projects
Four projects with the number each one moved. All figures are from production dashboards at the time of the change; company details are changed here because the work is under confidentiality.
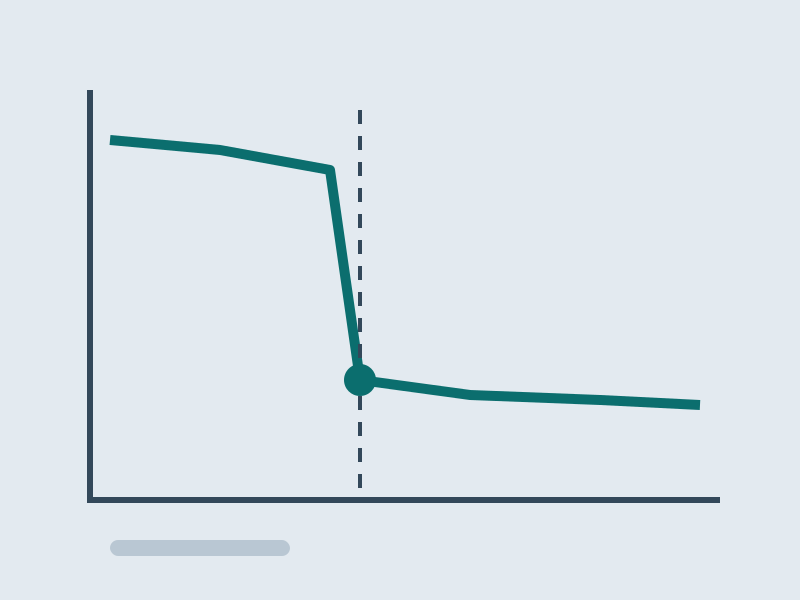
Search API: p99 latency from 840 ms to 210 ms 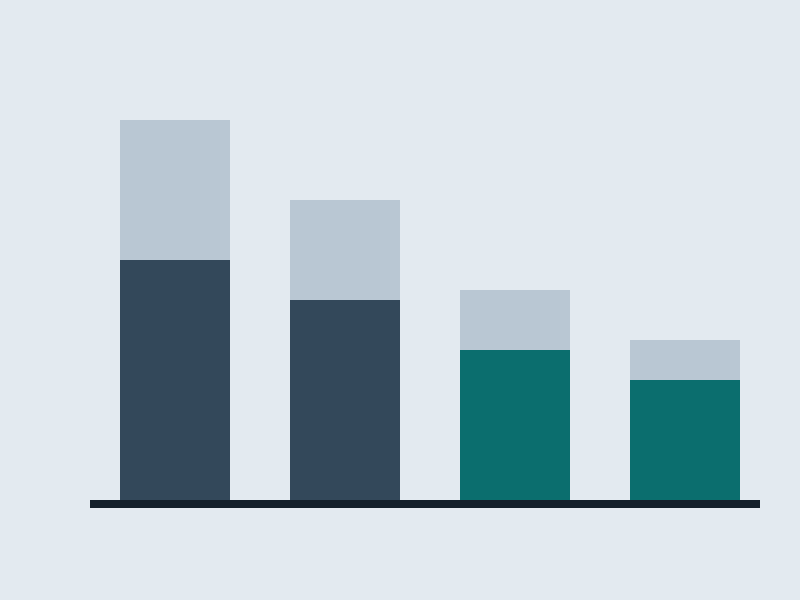
Cloud bill: 41% lower in a year while traffic grew 
Incident response: two bad days a year, not twelve 
Event pipeline: from 4,000 to 120,000 events a second
Career, by level
Staff engineer
Tallowmere CloudBristol, hybrid
– Present
Technical lead for the deploy platform and its three teams. Promoted after two years as a senior engineer there, on a case I wrote myself and that my manager and two other staff engineers reviewed.
- Cut the median deploy from 22 minutes to 6 across 140 services.
- Led the migration of 90 services to one service template; the on-call pager volume fell by a third.
- Run the yearly design review programme and mentor three senior engineers towards staff.
Senior engineer
Tallowmere CloudBristol, hybrid
–
Joined sideways at the same level I held before, for a larger platform and a path to staff.
- Redesigned the event pipeline from 4,000 to 120,000 events a second without a rewrite.
- Cut the cloud bill for the shared clusters by 41% in twelve months.
Senior engineer
Quillon SystemsBristol
–
Promoted after two and a half years. Quillon makes logistics software for 300 customers.
- Took the search API's p99 latency from 840 ms to 210 ms by fixing one query plan and adding a cache with a proper expiry.
- Introduced service level objectives; customer-visible downtime fell from twelve bad days a year to two.
Engineer II
Quillon SystemsBristol
–
Hired from a startup one level up from my old title, as a feature engineer on the booking service.
- Owned the booking service's database and moved it to a managed one with no downtime.
- Ran the first on-call rota for the team, with a written handover guide.
Software engineer
BrindlecastBristol
–
A 15-person startup selling scheduling tools. First job after university, with a title that said junior in all but name.
- Wrote most of the first public API and its test suite.
- Learned to run production the hard way, from the one on-call phone.
Tech stack
Languages
Cloud and infrastructure
Data and messaging
Observability
Delivery
Talks, open source and certifications
Talk: Paying for reliability you can measure
Westgate DevOps Day
Thirty minutes on setting service level objectives with a product team.
Maintainer, tracepipe
Open source
– Present
A small Go library for tracing pipelines, used by about 400 projects. Two co-maintainers, a release every six weeks.
Certified Kubernetes Administrator
Cloud Native Training Board
Passed first time; renewed in 2024.
MEng Computer Science, first class
Halvern Institute of Technology
–
Final-year project on scheduling jobs across unreliable machines.
Get in touch
I am happy to talk about platform work, reliability and how to grow as an engineer. Email is best; I reply within three working days.
- hello@rowan-ashdene.example
- Based in
- Bristol, UK; remote-friendly
- Talks
- Reliability, platform teams and career growth